Free
Basic checks for side projects.
$0/ month
No charge
Join early access- 5 uptime monitors
- 3-minute check interval
- Email alerts
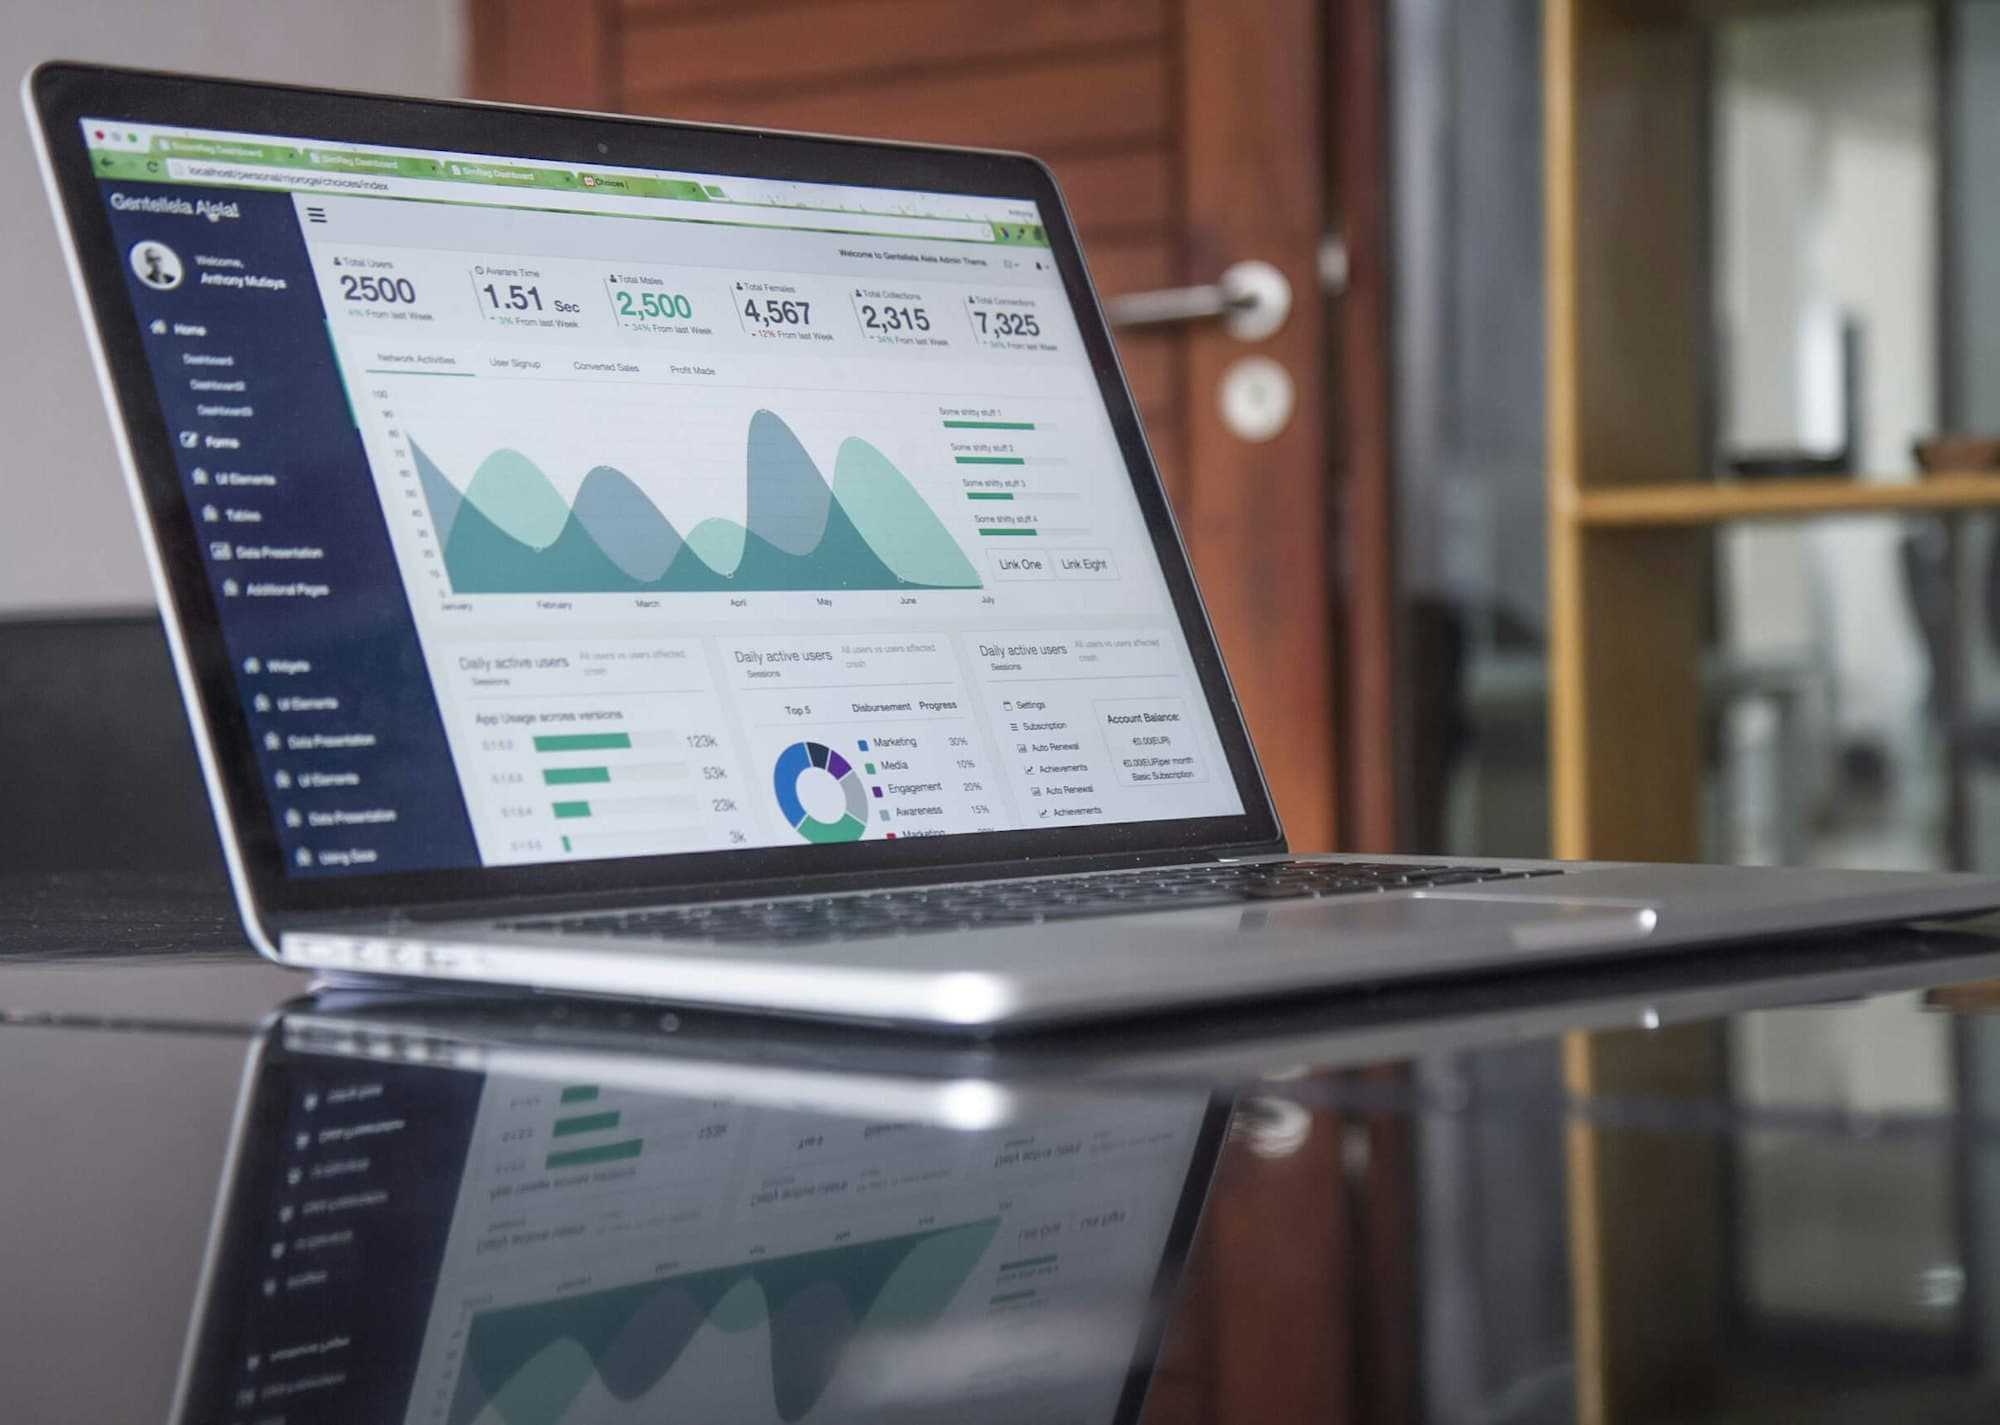
Papel Monitor, in early access
Papel Monitor checks your sites and APIs from several regions, groups errors from your code, pages the right person and keeps a public status page up to date.
The jobs Papel Monitor is designed to do, and the teams it suits best.
HTTP and keyword checks from several regions on your marketing site, sign-in page and API, with alerts only once a failure is confirmed.
Nightly imports, billing runs and backups ping a heartbeat URL. If one is late, someone hears about it before the morning.
Exceptions from web and mobile apps grouped by cause and tagged by release, so you can see which deploy introduced a problem.
B2B customers subscribe to incident updates instead of emailing support to ask whether something is wrong.
Probe endpoints from several regions. A failure is confirmed from a second region before anyone is alerted.
Assert that a page contains, or doesn't contain, a string, so a 200 response with an error page still counts as down.
Cron jobs and background workers ping a unique URL. If a ping is late, you get an alert.
Capture exceptions from JavaScript, Node.js, Python, Swift and Kotlin with stack traces and release tags.
Similar errors are grouped into one issue with a count, first and last seen, and affected users.
See which deploy introduced an error, and whether a fix actually made it go away.
Show the state of each component, with uptime history pulled from your monitors.
Customers subscribe by email or webhook and get notified when you post an incident or maintenance window.
Host the page at status.yourcompany.com with automatic HTTPS, on Business plans.
Send alerts to the channels your team already watches, with recovery messages when things come back.
Weekly rotations with overrides for vacations. Alerts go to whoever is on call right now.
If an alert isn't acknowledged in time, it escalates to the next person or the whole team.
Enter the URLs, ports or keywords to check, and the interval. Create heartbeat URLs for your scheduled jobs.
Add the SDK for your language with your project key. Tag events with the release version from your deploy pipeline.
Connect Slack, add phone numbers for SMS, and build an on-call schedule with an escalation policy.
When a check fails, a second region re-checks it. Confirmed failures open an incident and page the on-call person.
Post an update to your status page so subscribers are notified. When checks recover, the incident closes with a timeline.
How a failure becomes an alert and a status update. Signals come from your systems; Papel Monitor confirms them before anyone is paged.
Step 1: Your systems
Sites and APIs
Probed over HTTP, TCP or keyword checks.
Scheduled jobs
Ping a unique heartbeat URL on each run.
Your code
Error SDKs send exceptions with release tags.
Step 2: Papel Monitor
Multi-region checks
A failure is re-checked from a second region before an incident opens.
Error grouping
Similar errors combined into one issue with counts and affected users.
Incidents
A timeline from first failure to recovery.
Step 3: Alerting
On-call schedule
The alert goes to whoever is on call now.
Escalation
Unacknowledged alerts move to the next person.
Channels
Slack, SMS, email and webhooks.
Step 4: Your customers
Status page
Component status and uptime history.
Subscribers
Email or webhook notifications for incidents and maintenance.
SDKs strip common sensitive fields, such as passwords and authorization headers, before events leave your app.
Status pages are served from Papel Monitor, not from your own infrastructure, so they stay reachable when your app is down.
Error events are kept for 30 days on Team and 90 days on Business, then deleted.
What the people who own Papel Monitor in your company can configure, review and restrict.
| Service | What it does |
|---|---|
| Slack | Alerts, acknowledgements and recoveries |
| SMS and email | Direct alerts to the on-call person |
| Webhooks | Send incidents to any system |
| JavaScript and Node.js | Error tracking SDK |
| Python | Error tracking SDK |
| Swift and Kotlin | Mobile crash and error SDKs |
| GitHub | Link errors to releases and commits |
| Papel Cloud | Monitors created for each deployed app |
SDKs strip common sensitive fields such as passwords, card numbers and authorization headers before events leave your app.
Error events are kept for 30 days on Team and 90 days on Business, then deleted.
Event data is encrypted in transit with TLS and at rest on AWS.
Invite teammates with admin or member roles. Status page subscribers' emails are only used for status notifications.
More detail on our security practices and Privacy Policy.
Prices in US dollars, billed monthly. You aren't charged during early access until your workspace is live, and you can cancel at the end of any billing period.
Basic checks for side projects.
No charge
Join early accessProduction monitoring for a small team.
Billed monthly
Join early accessMultiple products and on-call rotations.
Billed monthly
Join early accessWhat each plan includes, side by side. Figures match our pricing page; if anything here and your order form differ, the order form applies.
| Limit | Free$0 per month | Team$12 per month | Business$39 per month |
|---|---|---|---|
| Uptime monitors | 5 | 50 | 250 |
| Fastest check interval | 3 minutes | 30 seconds | 30 seconds |
| Error events per month | Not included | 50,000 | 500,000 |
| Error event retention | Not included | 30 days | 90 days |
| Status pages | Not included | 1 | 5, with custom domains |
| Alert channels | Slack, SMS and email | Slack, SMS and email | |
| On-call schedules and escalation | Not included | Not included | Included |
See also our Acceptable Use Policy and Service Level Agreement.
Work we plan or are exploring, in no particular order. We don't promise dates: priorities follow what early-access customers ask for, and plans can change.
Warnings before TLS certificates or domain registrations expire.
A structured write-up attached to each incident, with the timeline filled in from monitoring data.
Probe locations beyond North America and Europe.
Alerts, acknowledgements and recoveries in Teams channels, alongside Slack.
Timing for slow requests and database queries, linked to the errors they cause.
From several AWS regions in North America and Europe. You choose which regions check each monitor.
A failed check is retried from a different region before an incident opens. You can also require several consecutive failures.
New events are sampled for the rest of the month rather than dropped entirely, and we email you before that happens. Uptime checks are never affected.
SMS alerts to US and Canadian numbers are included on Team and Business plans. Other countries may be limited during early access.
Yes. Growth and Scale development plans include monitoring for the apps we build and host for you.
Yes, if you allow traffic from our check locations. We'll share the current list of source addresses during onboarding.
Yes. Status pages are served from Papel Monitor, separate from your infrastructure, so customers can still reach them during an outage.
Yes. During onboarding we help you recreate your checks, alert routes and status page components, and you can run both in parallel until you're confident.
Tell us about your app and we'll set up your workspace with you. Billing starts when it's live.